Recovery First Ransomware Recovery Plan: RTO/RPO Checklist for IT
A ransomware recovery plan works when a company restores its systems from verified offline or immutable backups into a clean, isolated environment while preserving forensic evidence. The three moves that matter in the first hours: isolate every affected system before the encryption finishes spreading, triage assets by business impact rather than by what screams loudest, and confirm your backups are intact before you touch a single restore button.
TL;DR:
- Recovery plans must include clear decision authority, verified offline backups, and staged restoration to avoid reinfection and ensure rapid, clean system recovery.
- Backups should be immutable, air-gapped, or multi-site replicated, with regularly scheduled restore tests that verify data integrity and critical dependencies before an incident occurs.
- Isolating affected systems without powering down preserves volatile memory crucial for forensic analysis, requiring precise imaging and chain-of-custody procedures.
- An effective recovery environment must be pre-established with validated restore points, rotated credentials, and staged reconnection to monitor for reinfection.
- Decision-making during a crisis requires pre-authorized authority matrices, out-of-band communication channels, and regularly tested response procedures to prevent delays.
Table of Contents
- What Is a Ransomware Recovery Plan?
- Core Components Every Recovery Plan Must Include
- The Ransomware Attack Recovery Checklist: Minutes to Weeks
- Backup Architecture That Actually Survives an Attack
- Isolating Systems and Preserving Forensic Evidence
- Building a Clean Environment for Restoration
- Who Decides What During a Ransomware Crisis?
- How Often Should You Test a Recovery Plan?
- Turning the Incident Into a Hardening Roadmap
- Recovery Plan Templates and Implementation Notes
- Three Failures That Sink Recovery Efforts, and How Leaders Prevent Them
- Ready to Rebuild? Here's How Yslootahtech Helps
- Where to Verify the Details
- Sources
What Is a Ransomware Recovery Plan?
A ransomware recovery plan is the operational document that tells your team exactly how to bring systems back online after an attack, in what order, and under whose authority. It sits inside a larger cybersecurity incident response structure but has a narrower job: get the business running again on clean infrastructure, fast, without reinfecting anything.
That narrow scope matters because people conflate three documents that do different work. Incident response covers detection and containment: finding the intruder, cutting off their access, figuring out what they touched. Disaster recovery covers the technical restoration: rebuilding servers, restoring data, validating that systems function. Business continuity is the widest lens: how the company keeps serving customers and processing payroll while IT rebuilds everything behind the scenes.
The handoffs between these three functions cause more delay than the technical recovery itself. Incident response hands off to disaster recovery once containment is confirmed. Disaster recovery hands off to business continuity once core systems are verified clean. Skip a handoff, and you either restore too early into a still-compromised network or leave the business stalled longer than necessary.
Every recovery plan needs measurable targets, not vague ambition. That means:
- A Recovery Time Objective (RTO) for each critical system, meaning how long the business can tolerate that system being down.
- A Recovery Point Objective (RPO) defining how much data loss is acceptable, measured in time since the last clean backup.
- A prioritized asset list ranking systems by revenue impact, safety impact, and regulatory exposure, not by department politics.
Ready frames this correctly: start with an inventory of hardware, software, and data, then align recovery priorities to what the business actually needs functioning first.
Core Components Every Recovery Plan Must Include
Most recovery plans fail not because the concept is wrong but because the document is incomplete. A plan that only covers backups and skips decision authority collapses the moment three executives argue about who can approve a vendor payment at 2 a.m.
Here's what an operational plan actually needs, in full:
- Containment and isolation runbooks that specify exact switch-level and firewall actions, not general instructions to "isolate affected systems."
- Forensic evidence capture procedures with chain-of-custody steps, so evidence survives legal or insurance scrutiny later.
- Backup strategy documentation covering immutable and offline copies, plus how often each is verified.
- Recovery sequencing that defines the clean-rebuild environment and which admin accounts are trusted to operate in it.
- A roles and authority matrix naming who decides on containment actions, vendor engagement, and any ransom-related decision.
- Communications templates for internal staff, customers, regulators, and insurers.
- A testing cadence with named owners responsible for keeping the plan current.
CISA's Ransomware Guide prescribes a recovery sequence built around this exact structure: isolate impacted systems, triage and prioritize critical assets, image for forensics, then restore from verified offline backups into an isolated segment. That sequence is not optional guidance, it's the difference between a controlled recovery and a chaotic one.
The authority matrix deserves special attention because it's the piece most plans skip. Someone has to be authorized, in writing, before the incident, to shut down production systems without waiting for a committee vote. If that person doesn't exist on paper, you'll spend your most critical hours in a conference call instead of executing.
Pro Tip: Print your authority matrix and communications templates on paper and store copies offsite. If your network is encrypted, your digital copy of the plan is useless exactly when you need it most.
The Ransomware Attack Recovery Checklist: Minutes to Weeks
Recovery unfolds in phases, and the mistakes people make in hour one are different from the mistakes they make in week three. UpGuard's incident response checklist frames this as five stages: detection and validation, containment, eradication, recovery, and post-incident review. Here's how that plays out on a real clock.
-
0 to 4 hours: validate and isolate. Confirm the incident is real ransomware, not a false alarm from an overzealous antivirus alert. Disconnect affected systems from the network immediately, but avoid mass shutdowns that erase volatile memory you'll need later. Switch to out-of-band communications right away. CISA recommends using phone lines or a separate network for coordination during this window, because attackers monitoring your primary email or chat systems can accelerate destructive actions the moment they sense detection. Capture memory dumps and system logs from a representative sample of infected machines before anything gets powered down.
-
4 to 24 hours: triage against your critical-asset list. This is where your pre-built prioritization pays off. Systems tied to safety, revenue, and regulatory obligation get imaged and queued first. Everything else waits. Begin threat hunting across the broader environment, because ransomware operators frequently sit inside a network for days or weeks before triggering encryption, and the visible damage rarely marks the full extent of the compromise.
-
24 to 72 hours: forensic analysis and clean-restore confirmation. Your forensic team, internal or external, works to identify the last known clean restore point. This step gets rushed constantly, and it's the single biggest cause of reinfection. Veeam's recovery guidance makes the point plainly: success depends less on having backups than on confirming a restore point is actually clean before you use it. Simultaneously, stand up an isolated recovery network segment, and if the incident is severe enough, bring in a DFIR firm, legal counsel, and your cyber insurer during this window rather than after.
-
Days to weeks: staged restoration. Restore identity systems first, since nearly everything else depends on trusted authentication. Then core infrastructure, then critical applications, then general user access, watching closely for signs of reinfection at each stage before widening the blast radius of what's reconnected.
Each phase ends with a go or no-go decision, not an automatic progression. If forensic analysis can't confirm a clean restore point by hour 72, the answer isn't to proceed anyway, it's to extend the investigation and communicate the delay clearly to stakeholders. Organizations with tested backups and a documented plan recover measurably faster than those improvising in real time, according to TechTarget's ransomware recovery analysis, which also notes that paying the ransom doesn't skip these verification steps, it just adds a costly and unreliable detour before you reach the same cleanup work.
Backup Architecture That Actually Survives an Attack
Backups only count if the attacker can't reach them. Ransomware operators actively hunt for backup infrastructure before triggering encryption, specifically because a company with intact backups has no reason to pay them.
Three architectural patterns hold up under real attacks:
- Immutable storage, where backup data cannot be altered or deleted for a defined retention window, even by someone holding valid admin credentials.
- Air-gapped or air-gapped-like copies, physically or logically disconnected from the production network on a schedule.
- Multi-cloud or multi-site replication, so a compromise of one environment's credentials doesn't expose every copy of your data.
Golden images and infrastructure-as-code templates deserve a place in this architecture too, not just data backups. CISA and MS-ISAC's joint guidance specifically calls for keeping these templates, along with installers and license files, stored offline. Rebuilding a server is straightforward when you have a golden image. It becomes a scramble when your only path back is negotiating with a software vendor for reissued licenses during an active incident.
Protecting the backups themselves means segmenting credentials so that no single compromised account can reach both production and backup systems. Require multifactor authentication specifically for backup administration, separate from general network login, and restrict who holds that access to a small, named group.
Verification is the step everyone skips until it costs them. Microsoft's guidance on ransomware backup preparation is direct about this: having backups isn't sufficient, organizations need to actually exercise recovery procedures, including for cloud-managed data like OneDrive or SharePoint that people often assume is automatically safe. Automated restore tests, run on a schedule tied to how critical each system is, catch the silent backup failures that only surface during a real crisis otherwise.
Pro Tip: Schedule your most critical system's restore test regularly to surface missing dependencies before an actual attack. A scoped drill on a single application surfaces missing dependencies long before you're relying on it during an actual attack.
Retention policy needs a legal lens too. If backups become evidence in an investigation or insurance claim, your retention schedule has to account for that possibility rather than auto-deleting data on a fixed timeline that ignores an active case.
Isolating Systems and Preserving Forensic Evidence
The instinct to power everything off immediately is understandable and often wrong. Shutting down a machine erases volatile memory, and that memory frequently contains the encryption key fragments, active malware processes, and network connections investigators need to understand how the attack unfolded.
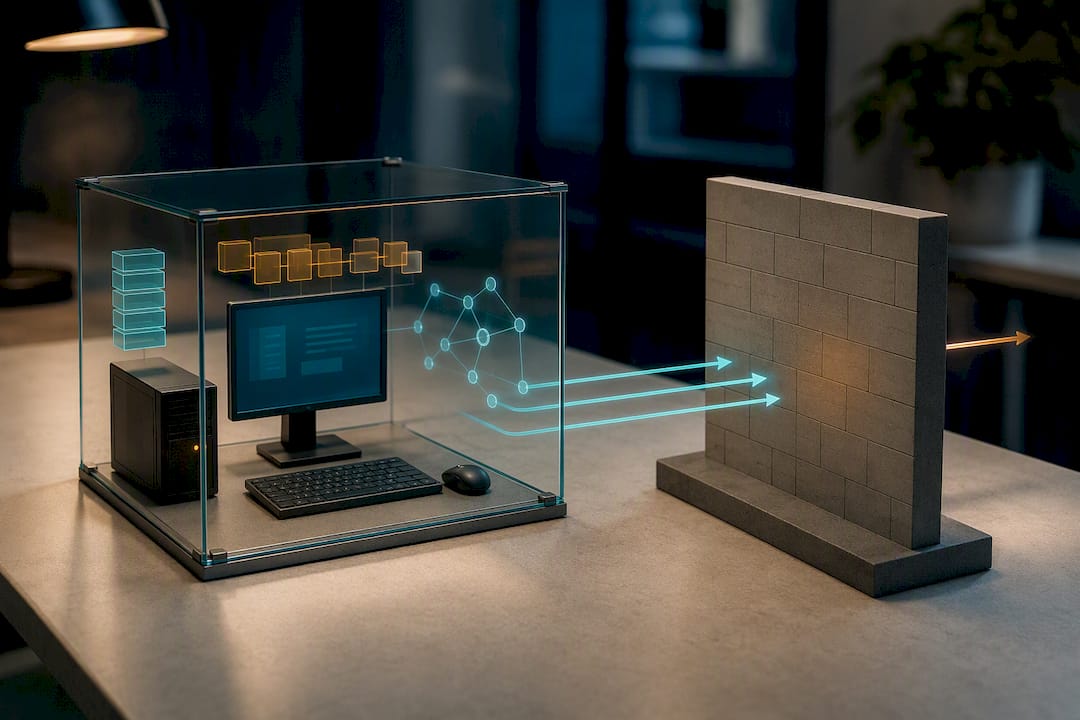
Isolation beats shutdown in most scenarios. Disconnect the network cable or disable the network interface, but leave the machine running long enough to capture a memory image. Reserve full shutdown for cases where a system poses an active, immediate threat, like actively spreading malware across a segment you can't otherwise contain.
Imaging practices differ slightly by system type:
- Endpoints need full disk images plus memory captures where feasible.
- Servers require the same, prioritized by which ones hold the data most critical to recovery.
- Cloud virtual machines need snapshot-based imaging through the cloud provider's native tools, since physical access isn't an option.
Collect ransom notes, indicators of compromise, and relevant logs across every affected system, not just the first one you find. Chain-of-custody documentation matters more than most IT teams initially assume, especially if law enforcement or an insurer later needs to verify how evidence was handled. Note who collected each piece of evidence, when, and where it's stored.
Bring in external DFIR specialists when the scope exceeds your internal team's forensic capability, or when the incident involves regulated data that will trigger mandatory reporting. Law enforcement involvement, typically through the FBI or a local cybercrime unit, becomes appropriate once you've confirmed the scope and have evidence organized enough to hand over productively. None of this should block your recovery timeline. Evidence preservation and system restoration can run in parallel once you've imaged the systems you need.
Building a Clean Environment for Restoration
Restoring into the same compromised network is how organizations get hit twice in one month. A trusted recovery environment, whether a segregated VLAN on-premises or an isolated cloud region, has to exist before the first restore begins, not get improvised mid-crisis.
The sequence that works:
- Stand up the isolated recovery network with new, rotated credentials for every administrative account that will touch it. Never reuse potentially compromised admin credentials in the clean environment.
- Validate each restore point against known indicators of compromise before deployment, scanning for persistence mechanisms that might have been backed up alongside legitimate data.
- Restore identity infrastructure first. Veeam's guidance on ransomware recovery is specific here: re-establish trusted identity, including rotated keys and validated admin accounts, before reconnecting anything else. DNS and core infrastructure come next, then critical business applications, then general user access.
- Run validation checks after every single restore step, not just at the end. Confirm the restored system behaves as expected and shows no signs of the original compromise before moving to the next tier.
- Reconnect in stages, monitoring network traffic closely for reinfection signals between each stage rather than flipping every system back online simultaneously.
Pro Tip: Treat identity restoration like a locked front door. Everything downstream depends on it, and rushing past it to restore "faster" usually means restoring twice.
Monitoring doesn't stop once systems are back online. Elevated logging and threat hunting should continue for weeks after reconnection, because a sophisticated attacker's secondary access points sometimes surface only after normal operations resume and their usual traffic patterns return.
Who Decides What During a Ransomware Crisis?
Recovery stalls most often on decision authority, not technology. Someone needs pre-authorized power to isolate systems, engage outside vendors, and weigh a ransom decision, all without waiting on a full executive vote while the clock runs.
Build a decision authority matrix that names specific individuals, by title, for each category of emergency action: network isolation, vendor engagement, ransom evaluation, and public communication. Back that up with out-of-band communication channels established before an incident, not scrambled together during one, plus holding statement templates for employees, customers, and press that need only minor editing under pressure.
Regulatory and insurance notification windows vary by jurisdiction and policy, but both typically expect a summary of evidence and a contact list ready quickly. Prepare that documentation structure in advance so you're filling in details during the incident, not building a template from scratch.
Third-party coordination needs its own line in the plan:
- Cloud providers, for platform-level incident support and forensic log access.
- Managed service providers, for scope clarification on what falls under their responsibility versus yours.
- DFIR vendors, ideally under a pre-negotiated retainer so engagement doesn't wait on a new contract negotiation mid-crisis.
How Often Should You Test a Recovery Plan?
A recovery plan that's never been tested is a hypothesis, not a plan. Testing happens in layers, and each layer catches different failures.
- Tabletop exercises walk leadership and IT through a simulated scenario verbally, testing whether the decision authority matrix and communication templates actually work under pressure. Run these quarterly.
- Scoped restore drills test one critical application's actual recovery process technically, surfacing missing dependencies or broken automation before a real incident exposes them. A monthly cadence for a single critical app catches problems far faster than annual testing alone.
- Full failover exercises simulate a complete recovery of critical workloads into the isolated environment, ideally semiannually for high-priority systems.
- Annual full-scale exercises stress-test the entire plan end to end, including third-party coordination and executive decision-making.
Track specific metrics across these exercises: mean time to recovery, restore success rate, time required to verify backup integrity, and whether RTO/RPO targets were actually achieved during the drill rather than just on paper. When a test surfaces a gap, whether it's a missing dependency or a communication template nobody could locate, that finding goes straight into a prioritized remediation backlog with an owner and a deadline, not into a report nobody reopens.
Turning the Incident Into a Hardening Roadmap
Every ransomware incident, successfully contained or not, generates lessons that most organizations fail to capture properly. A structured after-action review, run without assigning blame, maps the full attack chain from initial access to detection to recovery, with input from both internal stakeholders and any external DFIR team involved.
Prioritize the fixes that come out of that review by actual business impact, not by which fix is easiest to implement. Identity hardening usually rises to the top, since compromised credentials remain the most common entry point. Backup architecture changes, patching gaps, and vendor risk controls typically follow close behind.
Two structural actions matter beyond the immediate fixes:
- Share anonymized indicators of compromise with your sector's Information Sharing and Analysis Center, contributing to the broader defense community while protecting your own confidentiality.
- Update every runbook, playbook, and vendor contract that the incident revealed as outdated or incomplete, rather than filing the lessons learned report and moving on.
Lessons from a real incident carry more weight in a budget conversation than any theoretical risk assessment. Use that leverage. A hardening roadmap built from an actual post-incident review gets funded faster than a generic security wish list ever will.
Recovery Plan Templates and Implementation Notes
A recovery plan lives or dies on whether its templates get used correctly under pressure, not on how thorough the document looks in a binder. A few templates carry the most weight:
- A critical asset inventory template ranking every system by RTO, RPO, and business impact category, reviewed at least twice a year as infrastructure changes.
- A recovery sequencing checklist mapping the exact restore order, identity first, then infrastructure, then applications, then users, with a sign-off field after each stage.
- A backup verification test plan documenting test frequency, pass/fail criteria, and the owner responsible for each system's restore validation.
Implementation gets nuanced depending on where your infrastructure actually lives. On-premises rebuilds depend heavily on hardware availability and vendor support windows, which is exactly why offline installers and license files need to sit in escrow ahead of time. Cloud rebuilds move faster when infrastructure-as-code templates and golden images are maintained and tested regularly, since a clean environment can spin up in minutes rather than days. Partner platforms focused on enterprise IT readiness assessments can help organizations evaluate how prepared their broader technology stack is for exactly this kind of automated, template-driven rebuild.
Three Failures That Sink Recovery Efforts, and How Leaders Prevent Them
The pattern repeats across nearly every failed recovery I've studied: untested backups that turn out to be corrupted or incomplete, restoration sequences that skip identity systems and cause cascading access failures, and decision authority so unclear that hours vanish in debate instead of action.
None of these are technology problems. They're leadership problems. Fund restore testing as a recurring line item, not a one-time project. Mandate offline backups and golden images as policy, not best-effort recommendation. Require runbook sign-off from named executives and put quarterly exercises on the calendar before an incident forces the conversation. The organizations that recover fastest aren't the ones with the most expensive tools. They're the ones whose leaders treated testing as non-negotiable months before they needed it.
— YS
Ready to Rebuild? Here's How Yslootahtech Helps
Some technology partners provide IT leaders a faster path back to production by building and testing automation, golden images, and rebuild architecture before an incident, not during one.

Recovering from ransomware often exposes gaps that go beyond backups: outdated application architecture, brittle integrations, and front-end systems that weren't designed with rapid rebuild in mind. Technology partners may offer support through disaster recovery automation, infrastructure-as-code implementation for faster rebuilds, backup verification workflows, scoped restore drill design, application rebuilds and modernization, and recovery runbook development aligned with critical asset priorities.
If your last tabletop exercise revealed gaps in your application recovery path, or you're rebuilding after an incident and want the new environment more resilient than the one you lost, schedule a consultation on application development and start closing those gaps before the next attempt tests them for you.
Where to Verify the Details
For the authoritative version of any checklist in this article, go straight to the source. CISA's StopRansomware Guide remains the definitive federal reference for containment, forensic imaging, and restoration sequencing. The Ready.gov business recovery framework offers a solid structure for building your initial asset inventory and RTO/RPO targets. And Microsoft's Azure Well-Architected disaster recovery guidance is worth reviewing for runbook structure and failover design, particularly if your recovery environment includes cloud infrastructure.